RL and Distillation Build Different Reasoners From the Same Base
Divin Irakiza, September 2026
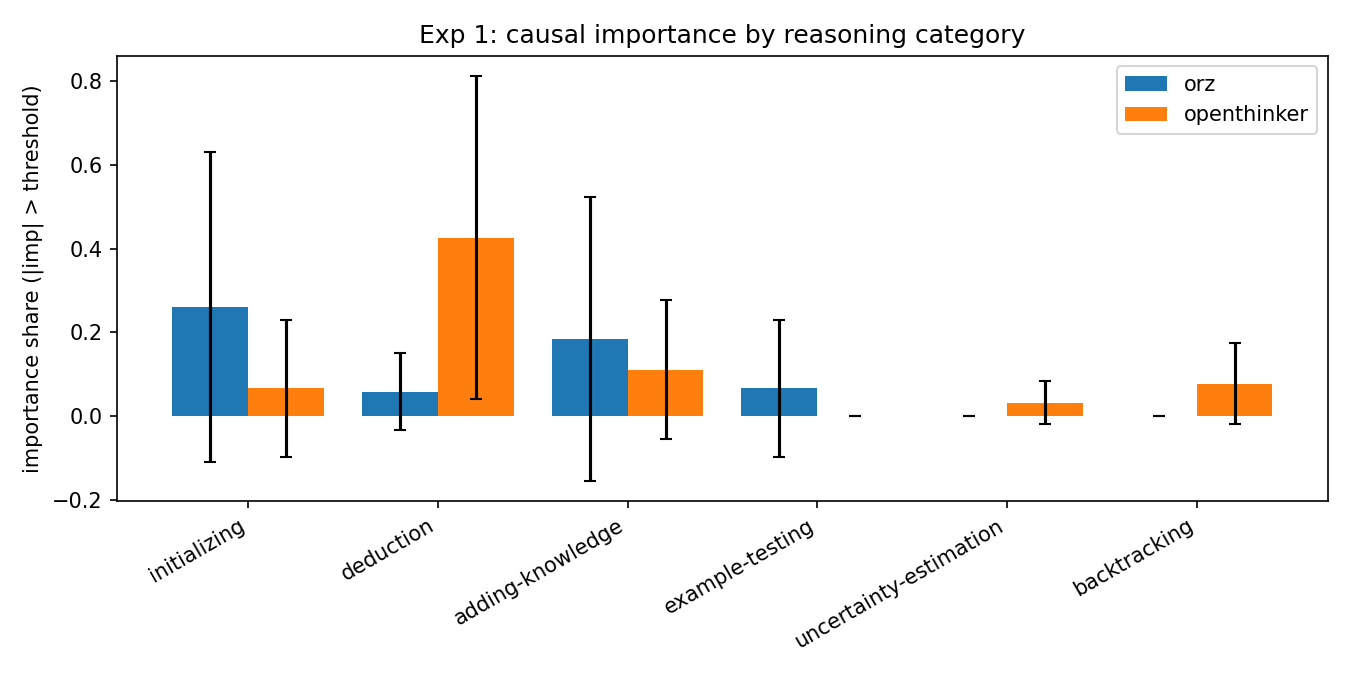
We find evidence that an RL-trained model and a distilled model built on the same base reason differently. The steps that causally determine their answers differ, and the RL model shows none of the distill's reflective behaviors. A steering vector for one of those behaviors doesn't transfer to the RL model at coherent strength, yet it still induces the behavior at higher strength, which suggests the capability is latent in the RL model but unused.